DNAOP — occupational-safety law library
We relaunched an open library of 45,294 Ukrainian occupational-safety regulations: a mobile-first design, search that understands how people look for norms, and every old address kept.
- Year
- 2026
- Scope
- Relaunch: design & build
- Type
- Regulations library
- Language
- Ukrainian
The site in numbers
A library people rely on, rebuilt from the ground up
DNAOP is an open library of Ukrainian occupational-safety regulations: NPAOP and DNAOP acts, building codes, standards, sanitary and fire-safety rules and ready-made safety instructions. Engineers and managers come for the exact wording of a norm — and need it on a phone as often as at a desk.
The old site still worked, but on an aging XSLT engine: no proper menu or mobile version, a mixed Russian and Ukrainian interface, tables drawn with dashes and thousands of pages with broken encoding. We rebuilt the library from scratch on a modern stack — and moved it without losing a single address.
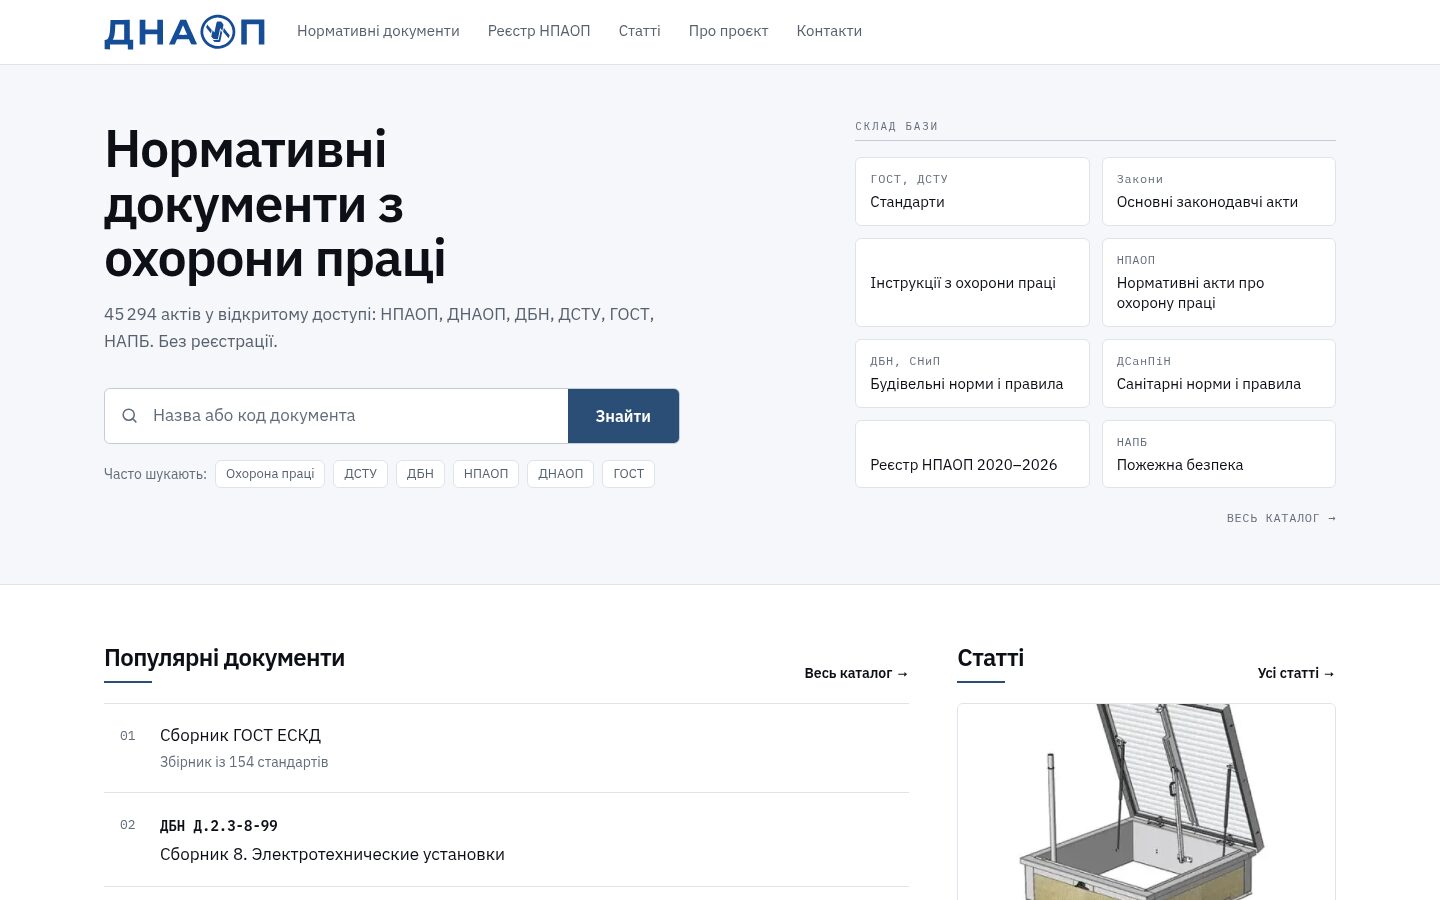
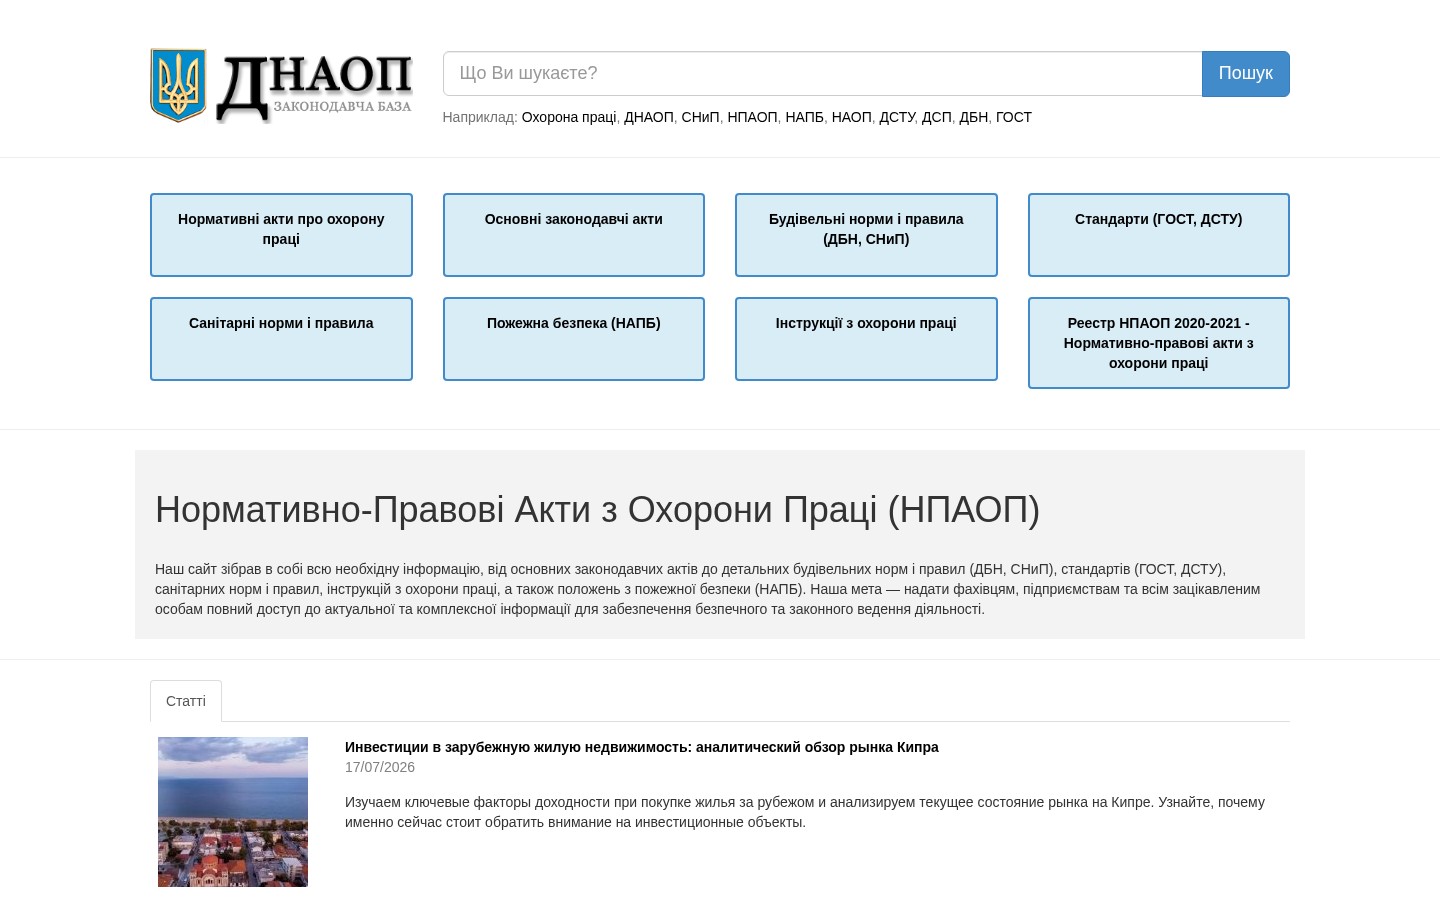
Old site and new — drag the slider
An act page you can actually read
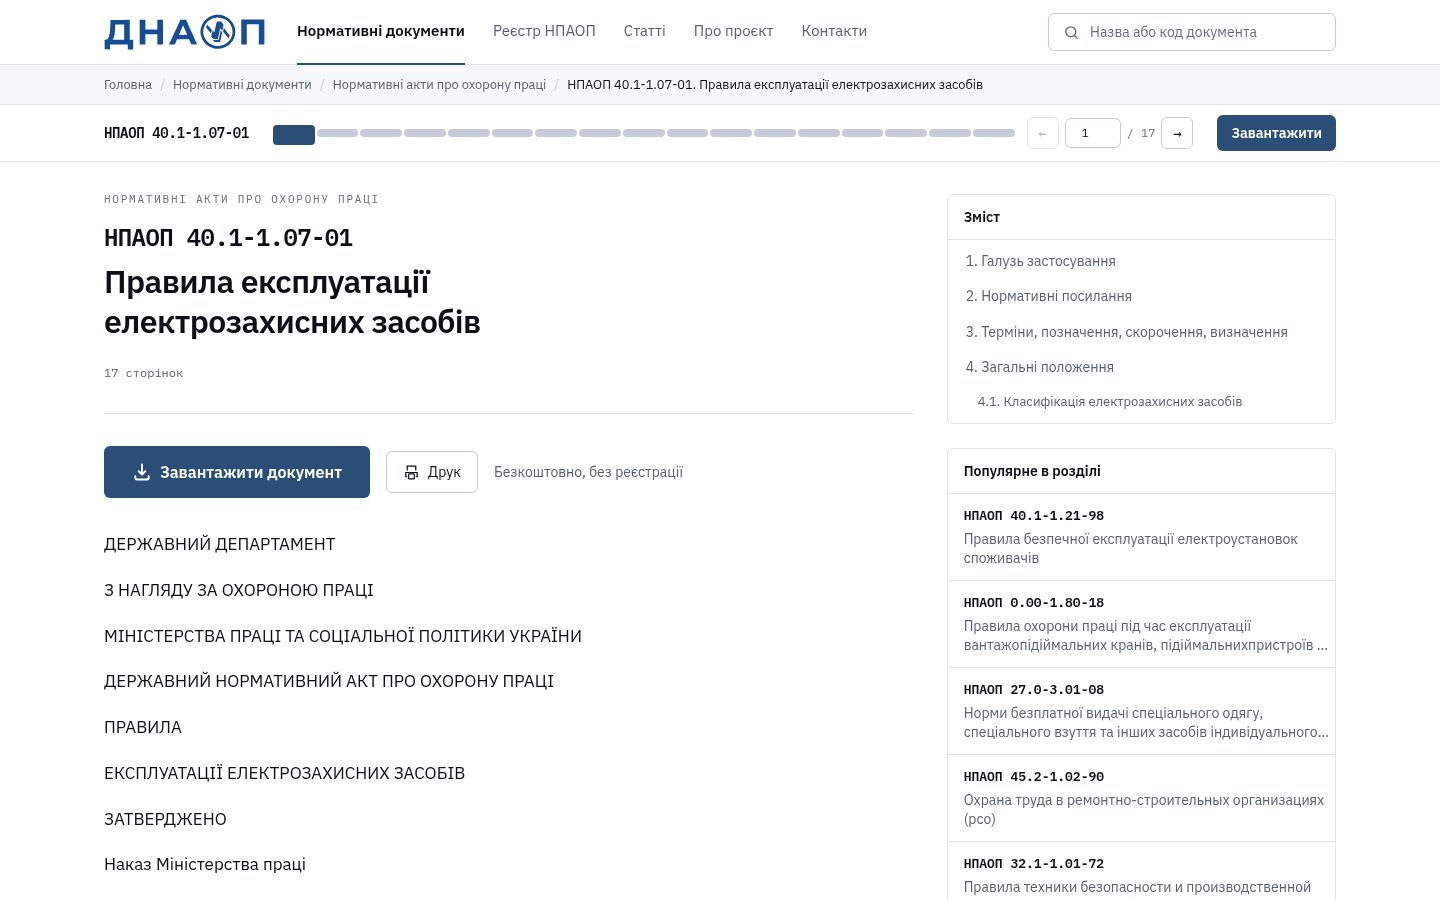
Regulations run to dozens of pages, the longest to 247. Every act now opens with a sticky page scale, a table of contents and a comfortable reading column; acts longer than 60 pages get a quick-jump row. Download and print are a tap away — free and without registration.
- A page scale in three modes, depending on the length of the act
- A table of contents and “See also” acts from the same series
- Works even with JavaScript turned off
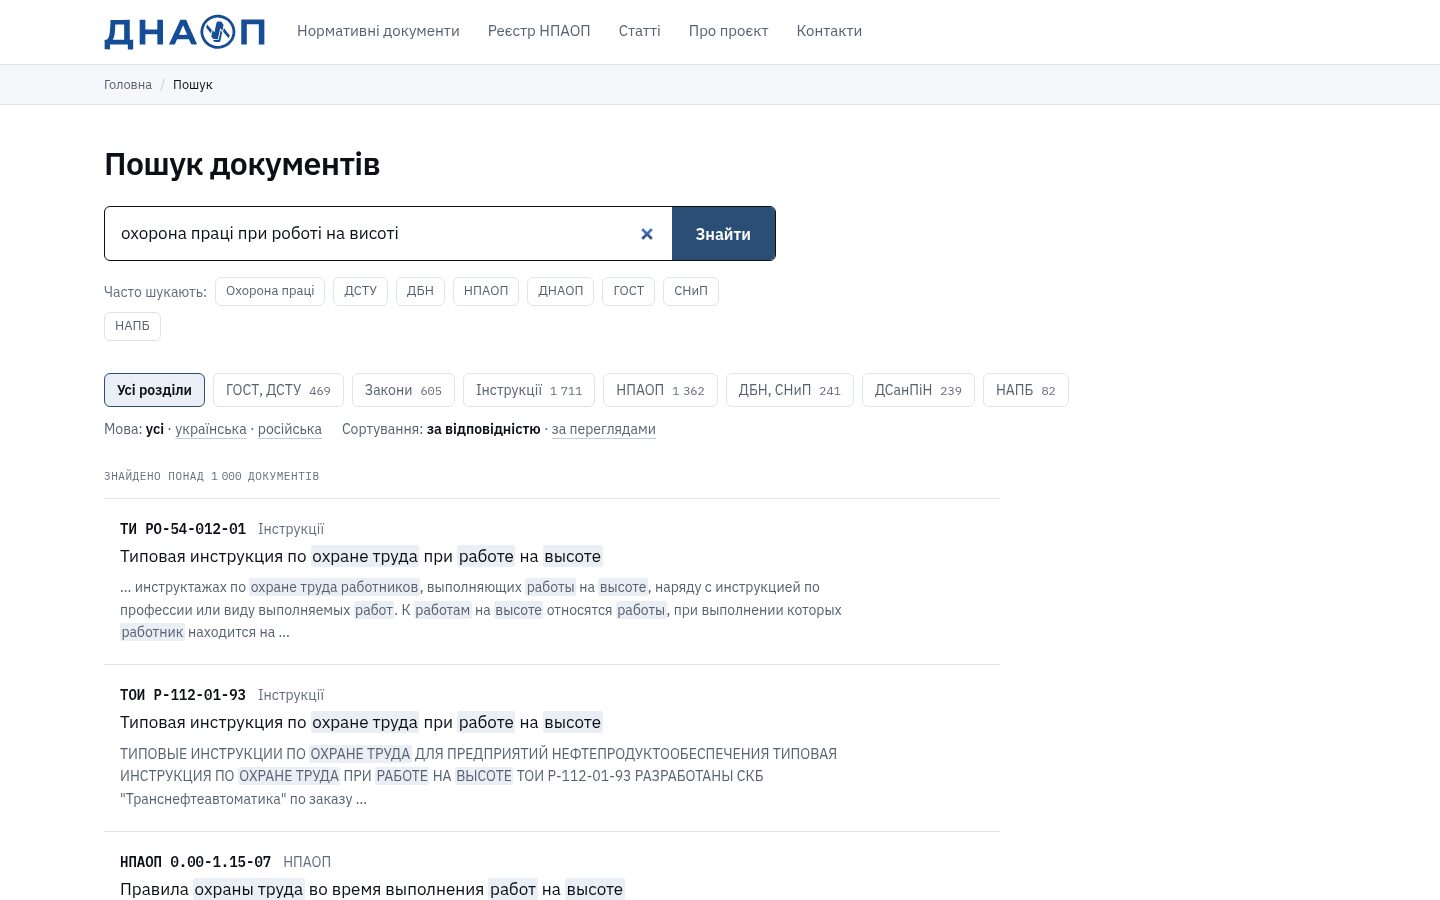
Search that understands how people look for norms
Readers search by a code like “NPAOP 40.1”, by a fragment of a title, or with a typo typed in the wrong keyboard layout. The new full-text search handles all of it across every page of every act and answers in tens of milliseconds. On a control set of queries, the right act comes first in 91% of cases and is always in the top three.
- Word forms in Ukrainian and Russian, exact match by code
- Typo and keyboard-layout correction, suggestions as you type
- Filters by section and language, highlighted matches
Forty-five thousand documents, repaired
Tables restored
2,571 acts with tables drawn in dashes now hold 47,837 real tables.
Texts re-extracted
1,578 acts were extracted again from the original Word archives, with strict checks.
Encodings and titles
191 acts with broken encoding and 886 titles missing their first letter were fixed.
Lighter images
32,828 images converted to WebP — the volume halved, from 1,060 to 521 MB.
Every address kept
167,714 URLs moved one-to-one and were checked against a week of real request logs — zero errors.
Search engines in the loop
Legislation markup, canonical tags, a sitemap rebuilt daily and IndexNow notifications on every change.
4.7 GB of texts, served in milliseconds
The library runs on Laravel 13 with a dedicated full-text search engine and caching at every level: rendered acts are served through a CDN, so a page that took 0.20 s now arrives in 0.06 s. The 4.7 GB of original texts were not forced into a database — they are cleaned on the fly and cached, while the sources stay untouched.
Editors work in a separate admin built with React and Fluent UI: documents and duplicates, articles with a visual and code editor and version history, pages, menus, media, redirects and enquiries — with five roles and an activity log. The public pages ship about 3 KB of our own JavaScript, and nearly 600 automated tests guard the whole thing.
A big site on an aging engine?
We’ll move it to a modern platform and keep its addresses and content intact.
Get in touch
Have a project in mind?
Tell us about it.
We reply within one business day